Skip to content
Next Robot
// Next Robot Local AI · Office Edition

An AI supercomputer in your office

We connect the server, tune the neural networks and build AI employees for your tasks. 100+ models and 50+ agents work inside your network.

#01RTX 5090 · 24 GB GDDR7#0250+ AI agents#03Up to 25 employees
See the hardware
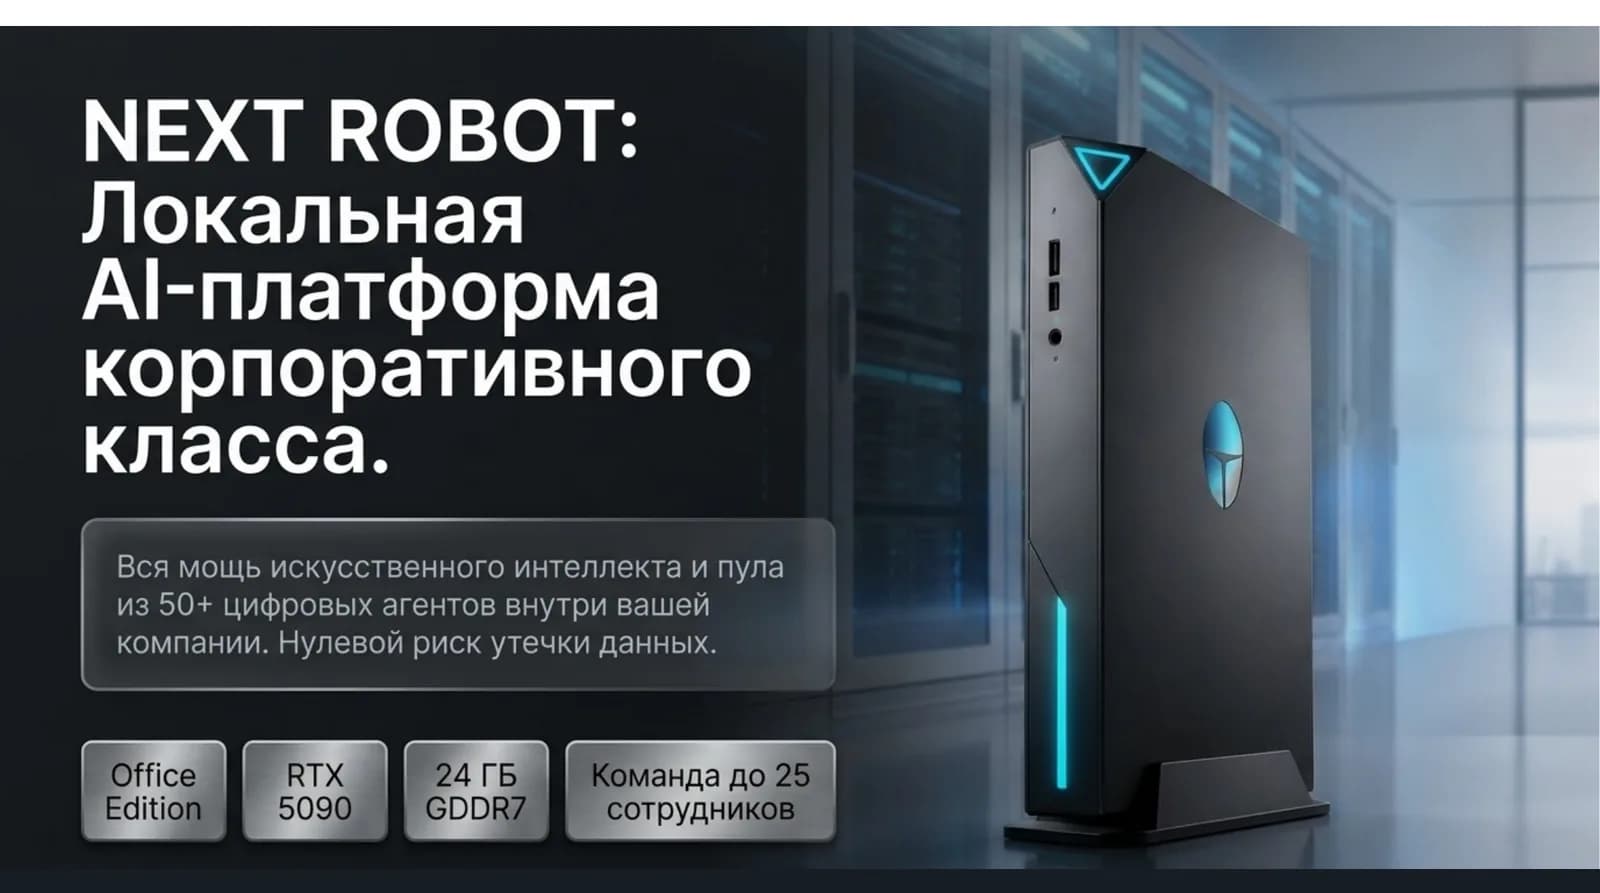
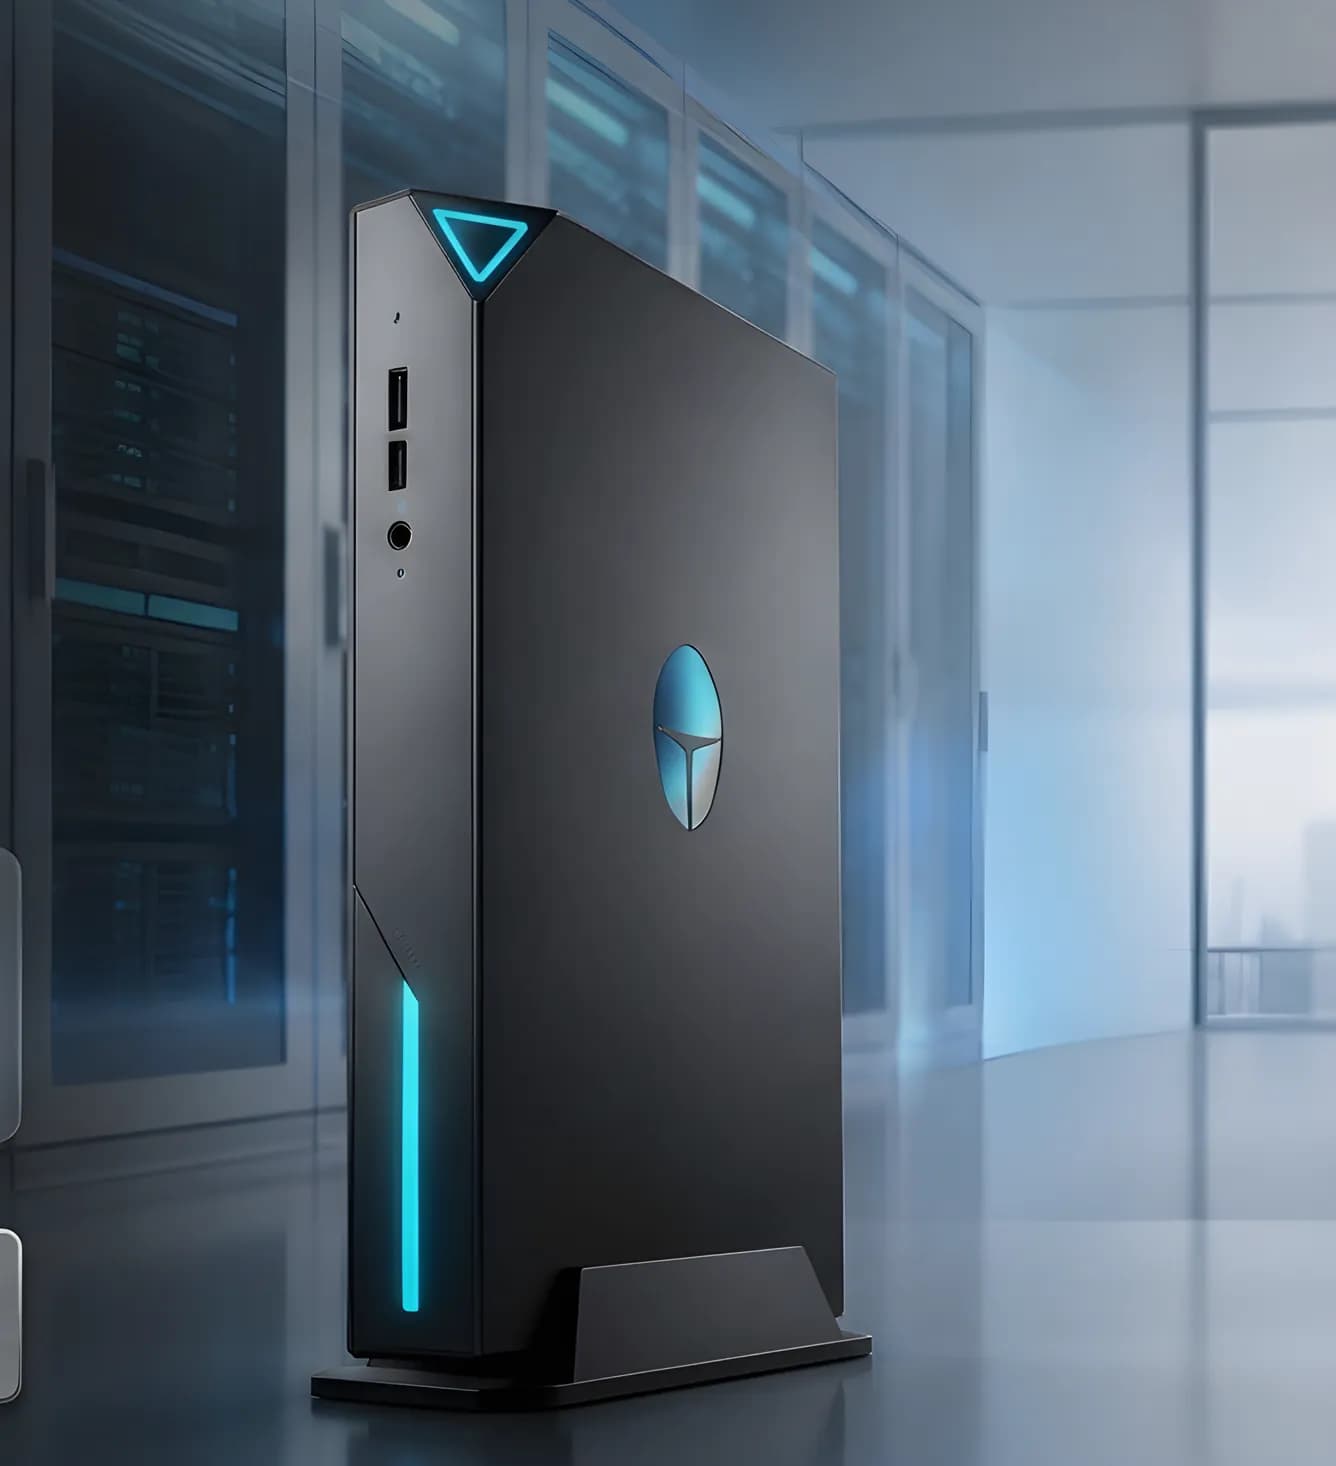
Compact Next Robot Local AI server with a cyan triangle logo in a server room
Perimeter · securedData stays on-site
50+ AI agentsOn the server · 24/7
// What we do

A supercomputer in your office. Turnkey, in four steps.

  1. 01

    We connect

    The server goes into your office and links to your network, email, CRM and ERP.

  2. 02

    We tune the models

    Local models, the load balancer and a cloud gateway set by your policy.

  3. 03

    We train on your data

    A knowledge base with RAG and OCR, roles and access rights for every department.

  4. 04

    We build AI employees

    Lawyer, finance, sales, HR and engineering agents take over routine work.

// Hardware

The hardware heart of local AI.

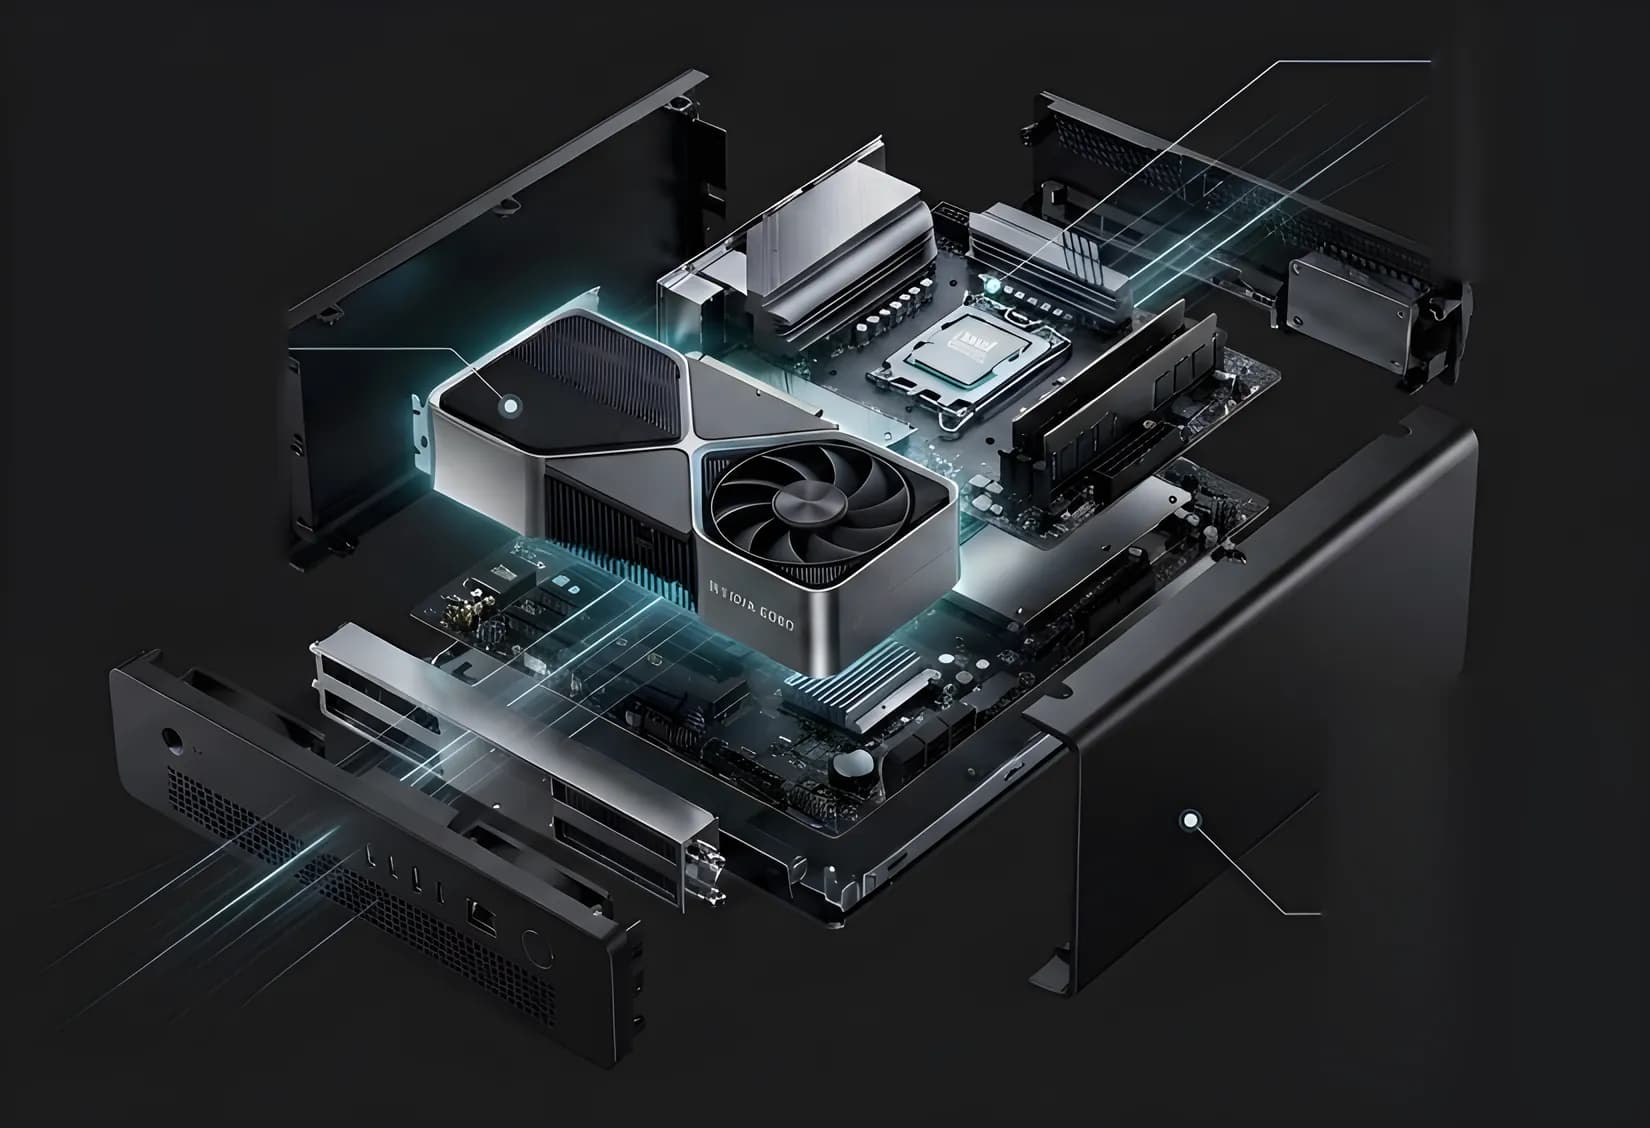
The RTX 5090 accelerates text generation, vision, OCR, embeddings and agent workflows. Enhanced cooling keeps the compact case office-ready.

Exploded view of the Next Robot Local AI server: NVIDIA RTX 5090 graphics card, Intel Core Ultra 9 processor and memory
Graphics
NVIDIA RTX 509024 GB GDDR7 · 10,496 CUDA cores
Processor
Intel Core Ultra 9 275HX24 cores · up to 5.4 GHz
Memory
64 GBRAM
Storage
1 TB NVMePCIe 4.0
Case
≈3 L332 × 212 × 45 mm · enhanced cooling
Power
230 W175 W GPU TDP
// Data sovereignty

Three levels of protection. Every file stays yours.

Models, search and agents run on your hardware. Every request is processed inside your network.

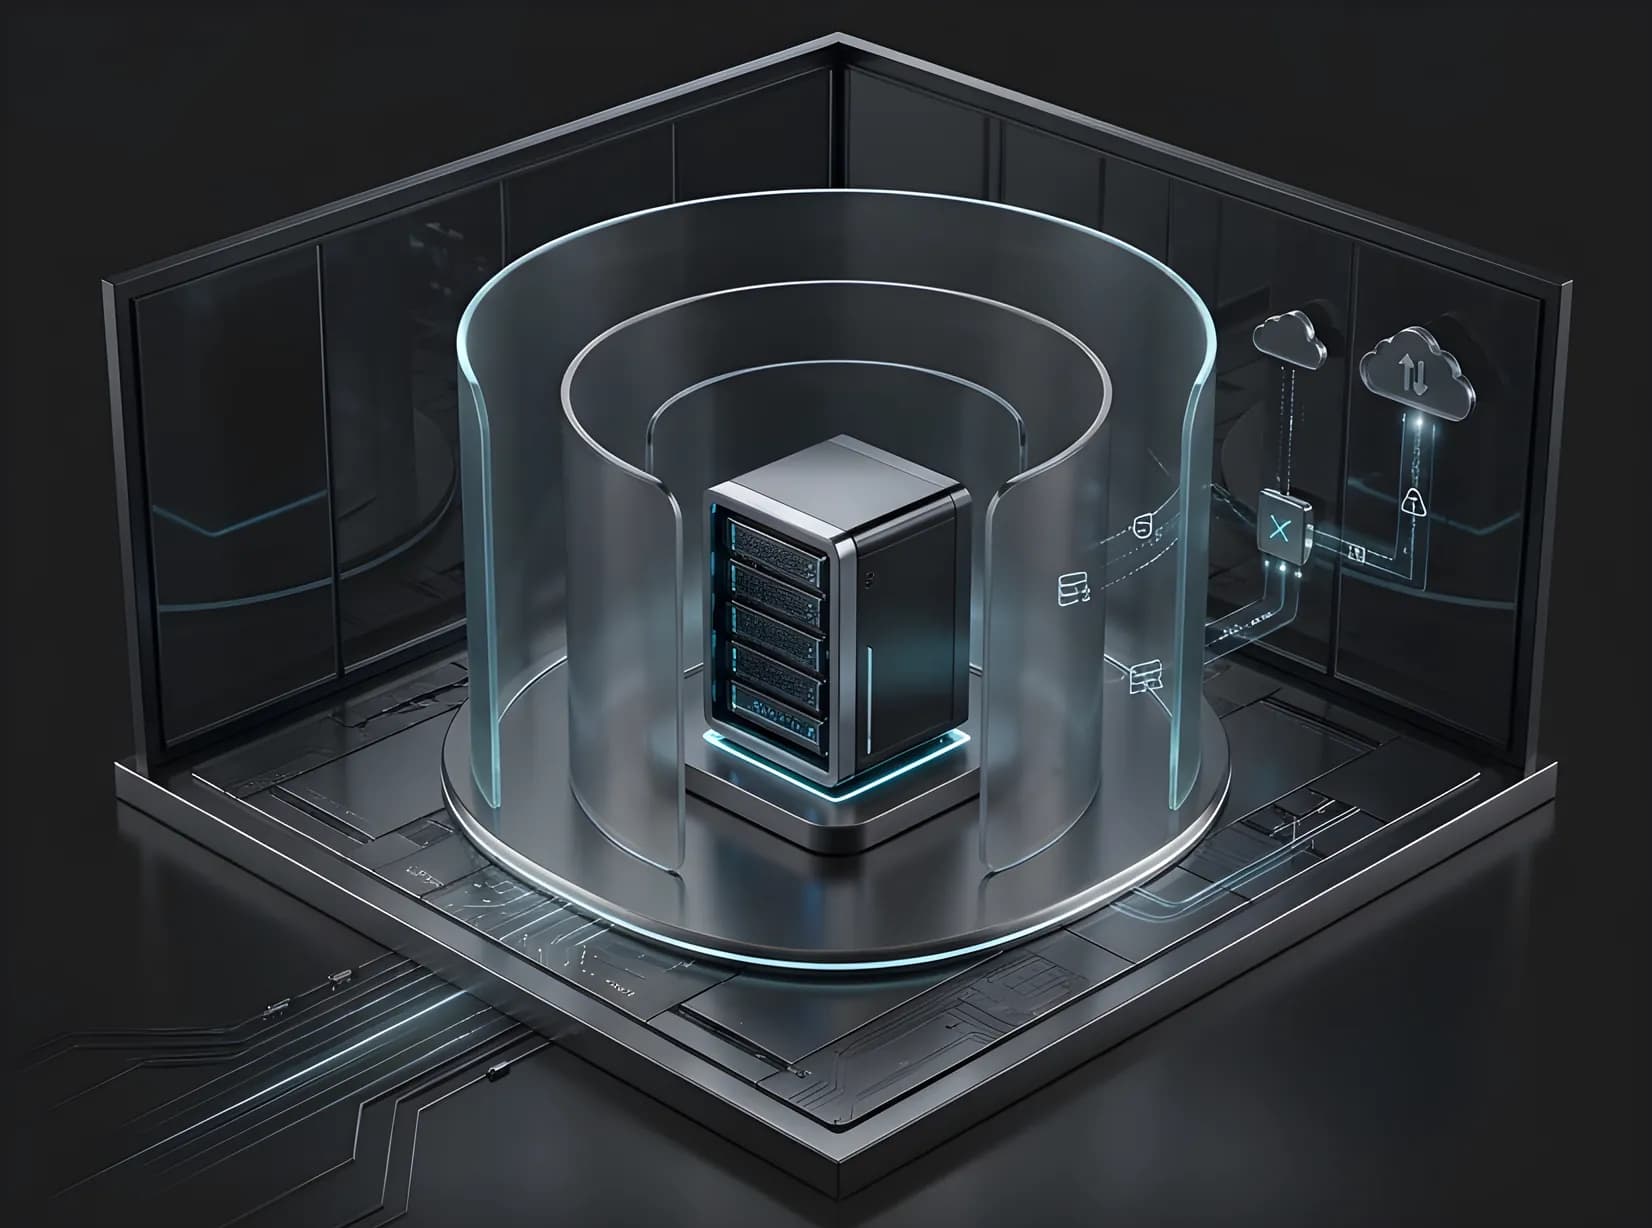
A server inside a protective perimeter: three levels of data protection
  1. 01 / 03

    Physical perimeter

    The server sits on your network. Files, requests and the knowledge base physically stay in your office.

  2. 02 / 03

    Encryption & access

    TLS 1.2/1.3, BitLocker disk encryption, VPN, SSO and strict role separation.

  3. 03 / 03

    Controlled cloud

    External models join only by your policy, through a secure gateway that masks sensitive data.

// Law & data

Data stays in the country. Built to meet Russian data law.

Personal data, trade secrets and documents are stored and processed on a server in your office. For companies in Russia this covers the key legal requirements; elsewhere the same on-premise design keeps data in your jurisdiction.

  • 152-FZ · Art. 18

    Personal data localisation

    Russian citizens’ personal data is recorded, stored and processed in a database inside Russia — on the server in your office. The rule applies as amended from 1 July 2025.

  • 152-FZ · Art. 19

    Protection measures

    Disk and channel encryption, role-based sign-in with SSO and an action log for every user and agent cover the key technical measures of Government Decree 1119 and FSTEC Order 21: identification, access control and event logging.

  • 98-FZ

    Trade secrets

    Contracts, finance and correspondence are processed by local models inside your perimeter, so your trade-secret regime stays intact.

  • 149-FZ

    Information protection

    As the information owner, you set access yourself: roles, department quotas and the cloud gateway policy.

  • Air-gapped

    Isolated mode

    Local models, speech recognition and knowledge-base search work in a fully isolated network for sites with strict security requirements.

Organisational measures, such as the personal-data policy and the notice to Roskomnadzor, are prepared by the data operator for its own profile. We hand over a description of the architecture and protection measures for that document set.

Federal Laws 152-FZ “On Personal Data” (as amended from 1 Jul 2025), 98-FZ “On Trade Secrets”, 149-FZ “On Information, Information Technologies and Information Protection”; Government Decree 1119; FSTEC Order 21.

// Smart routing

25 employees work at the same time.

The load balancer spreads requests across models: everyone gets a fast answer, and heavy tasks run in the background.

The load balancer routes employee requests to the right neural networks
  • One portal

    Employees send requests through the browser, the API or OpenCode.

  • Load balancer

    The system reads the task type and routes it to the right model: Qwen, RAG or Ollama.

  • Queues & priorities

    Chats answer instantly. Long multi-page documents are analysed in the background.

  • Quotas & roles

    Each department works with its approved models and databases.

// Neural networks

100+ neural networks in one window.

New models appear in the familiar interface, so your team keeps working the same way.

On the server · RTX 5090

Open-source models run locally

  • Qwen 3.8
  • Qwen Coder
  • Llama 4
  • Gemma 4
  • Nemotron
  • Whisper
  • FLUX
  • GLM-OCR
Western cloud

Controlled API, by your policy

  • GPT-5.6
  • Claude Opus
  • Claude Sonnet
  • Gemini 3.1 Pro
  • Mistral
Chinese cloud

Alternative controlled API

  • Qwen Max
  • DeepSeek V4 Pro
  • GLM 5.2
  • Kimi
Models matched to tasks
Qwen 3.8
Legal and business analysis, answers from the knowledge base
Qwen3 Coder 30B
Code generation and refactoring
Qwen3-VL 30B
Vision: diagrams, screenshots, document photos
gpt-oss 20B
Reasoning and agent workflows
GLM-OCR
Scans: structure, tables, metadata
Qwen3 Reranker · Qdrant
Knowledge-base search that respects access rights
Nemotron Streaming 3.5 · Whisper Large v3 Turbo
Speech recognition on the server
FLUX
Image generation
// AI employees

50+ agents across your departments.

Dozens of full-time roles by volume of routine work — 24/7, on-premise and by your corporate rules.

The Next Robot AI agent core with departments around it
  • LawyersContracts, risks, redline comparison
  • FinanceTable reconciliation, plan vs actual, anomalies
  • EngineersCode generation, review, documentation
  • HRCV screening, onboarding, policy base
  • SalesProposals, CRM call analysis
AI engineering team
Qwen3 Coder 30B · Qwen3-VL 30B · gpt-oss 20B
  • Solution architectSystem design
  • Backend / FrontendCode generation and refactoring
  • DevOpsLog analysis, Docker, CI/CD
  • QATest automation, diff review
  • Tech supportIncident and screenshot analysis

Agents work in parallel. A responsible engineer confirms every infrastructure and code change.

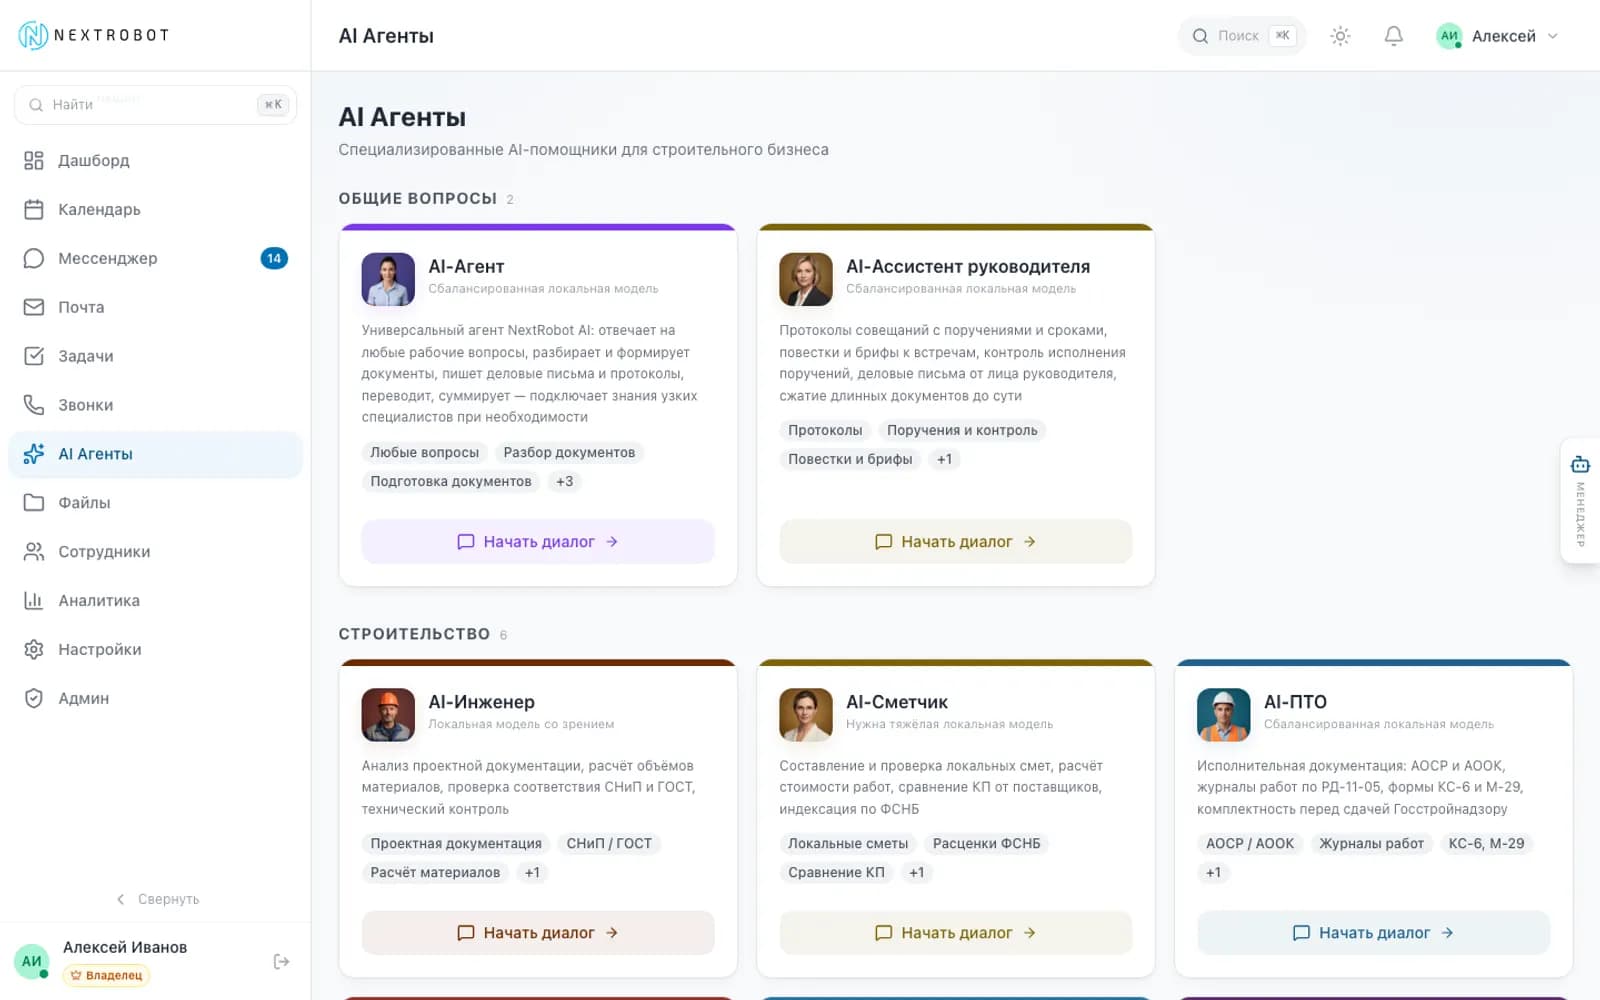
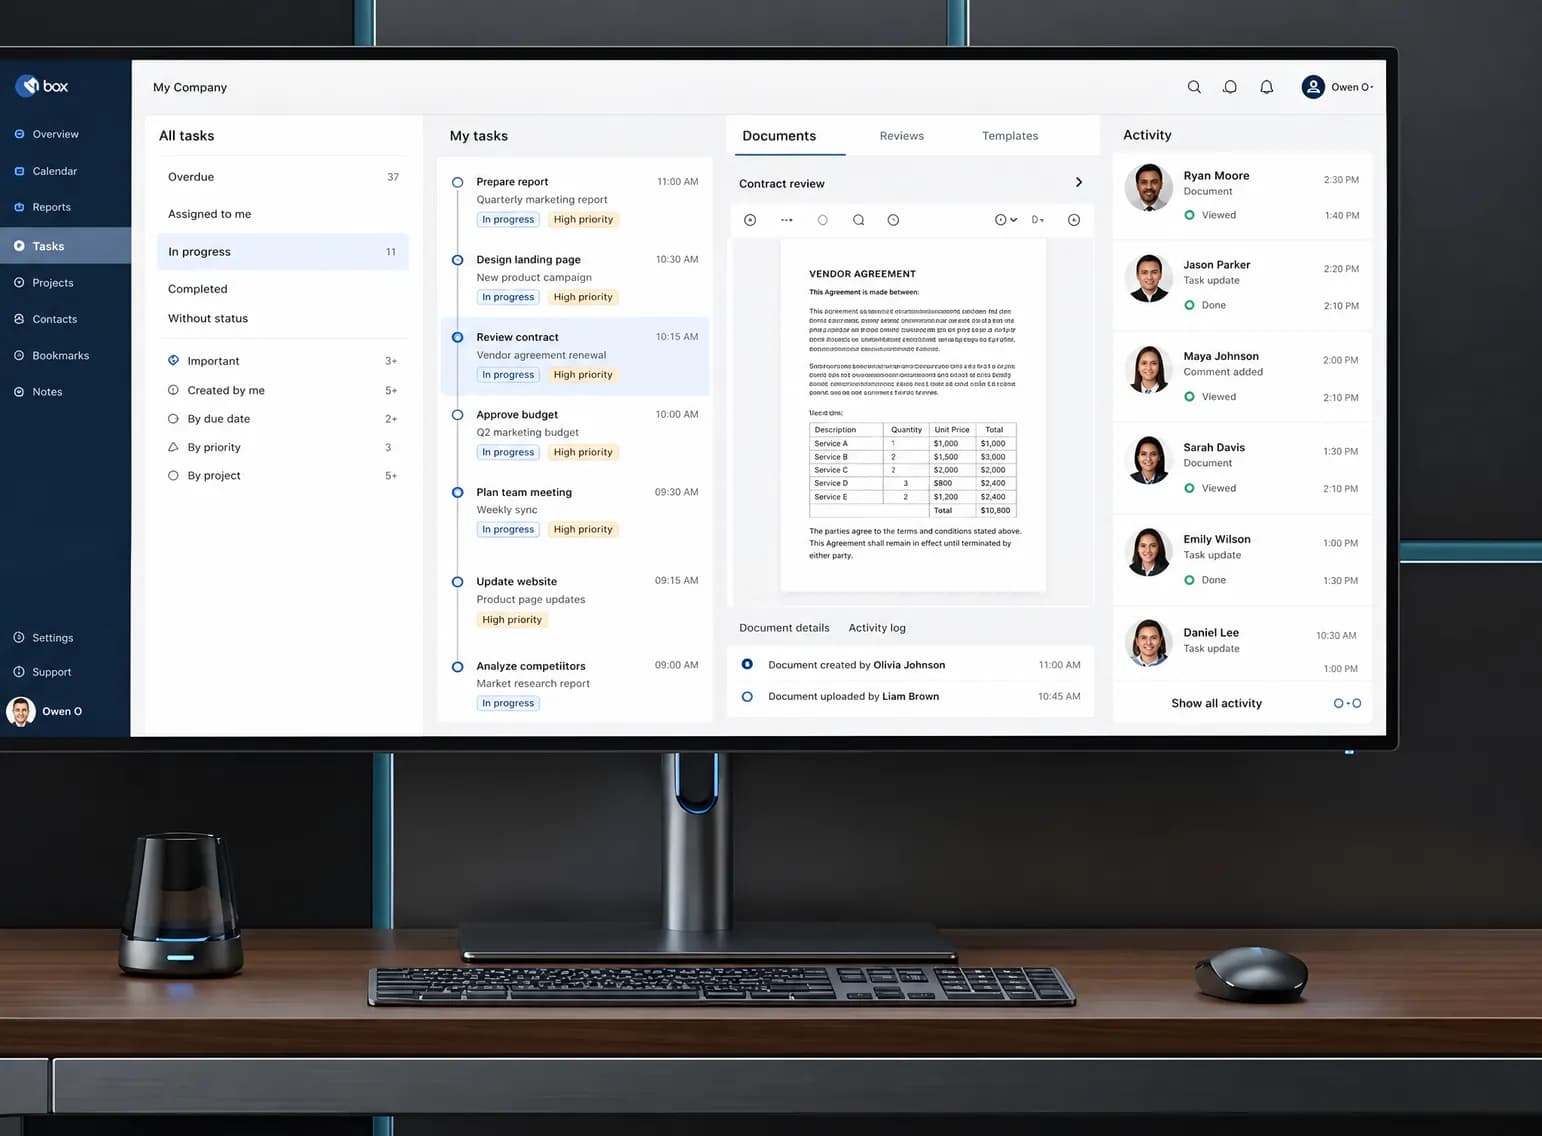
Next Robot agent portal: AI agents for managers, engineers and estimators
Agent portal · live interface
A vector knowledge base: finding the exact passage across documents
// Knowledge base

Answers with an exact quote from your documents.

RAG finds the precise passage and links to the source.

  1. 01

    Index

    The company knowledge base becomes vector layers — embeddings in Qdrant — with access rights preserved.

  2. 02

    Search

    Qwen3 Reranker filters the noise and finds the relevant paragraphs.

  3. 03

    Answer

    The model builds its answer from the passage found and adds a clickable link to the source.

// Voice

Voice is a full interface to your corporate AI.

A voice waveform flowing into a voice AI control panel
  • On-device recognition

    Nemotron Streaming 3.5 and Whisper Large v3 Turbo recognise speech right on the server, inside an isolated network.

  • Voice commands

    “Open the contract, find the risks, write a report” — dictate tasks, launch agents and switch models by voice.

  • Office AI operator

    Answers by voice, holds a dialogue, records agreements and works as a full assistant.

// Workspace

One work screen. Full human control.

  1. Brief

    Upload a document or set a task by text or voice.

  2. Auto-select

    The system picks the right agents and the best model.

  3. Transparency

    Status, intermediate results and a full log of agent actions.

  4. Human in the loop

    Final approval of deals and decisions stays with your employee.

A desk with the Next Robot agent portal on the monitor
// Scenarios

How it works on real tasks.

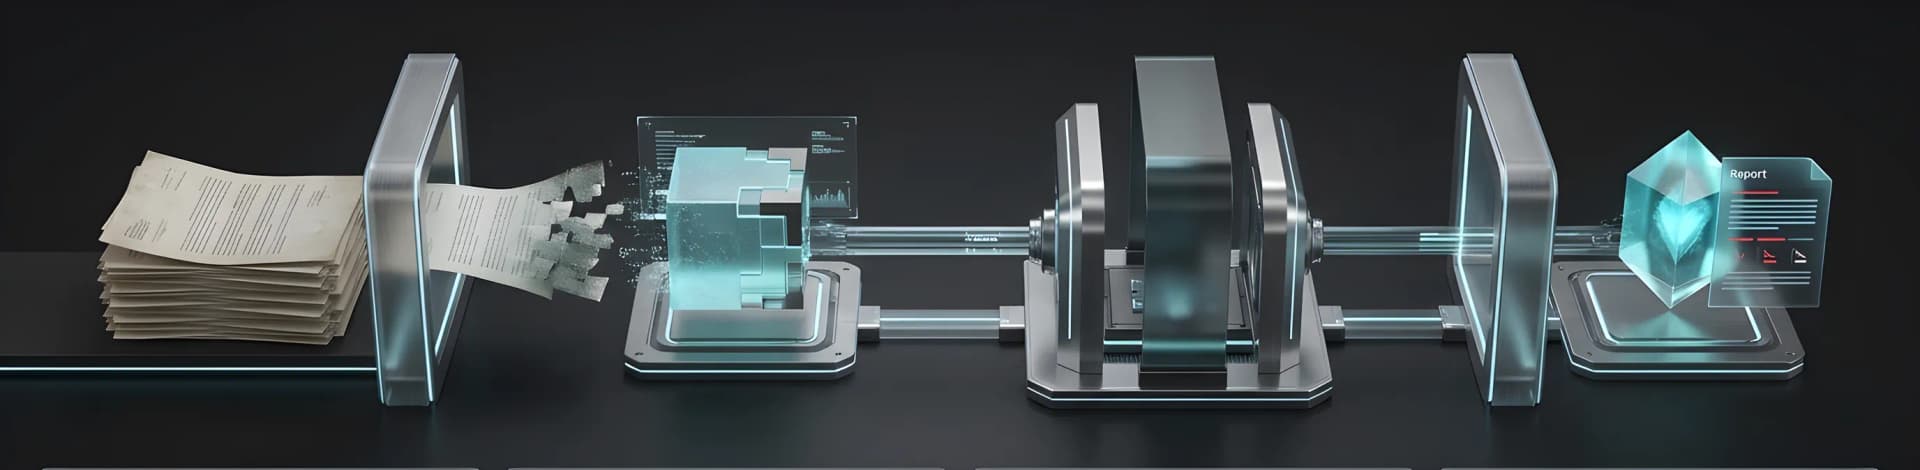
Complex deal audit

A contract pipeline: scan, OCR, lawyer agent, report
  1. 01 · Local network

    Upload

    A multi-page PDF scan goes into the portal on your network.

  2. 02 · GLM-OCR

    Recognition

    Structure, tables and metadata are digitised.

  3. 03 · Lawyer agent · Qwen 3.8

    Analysis

    Obligations, deadlines and restrictions are checked against your local reference base.

  4. 04 · Human in the loop

    Report & redline

    Risks with exact quotes and a new wording. Your lawyer makes the call.
Financial analysis

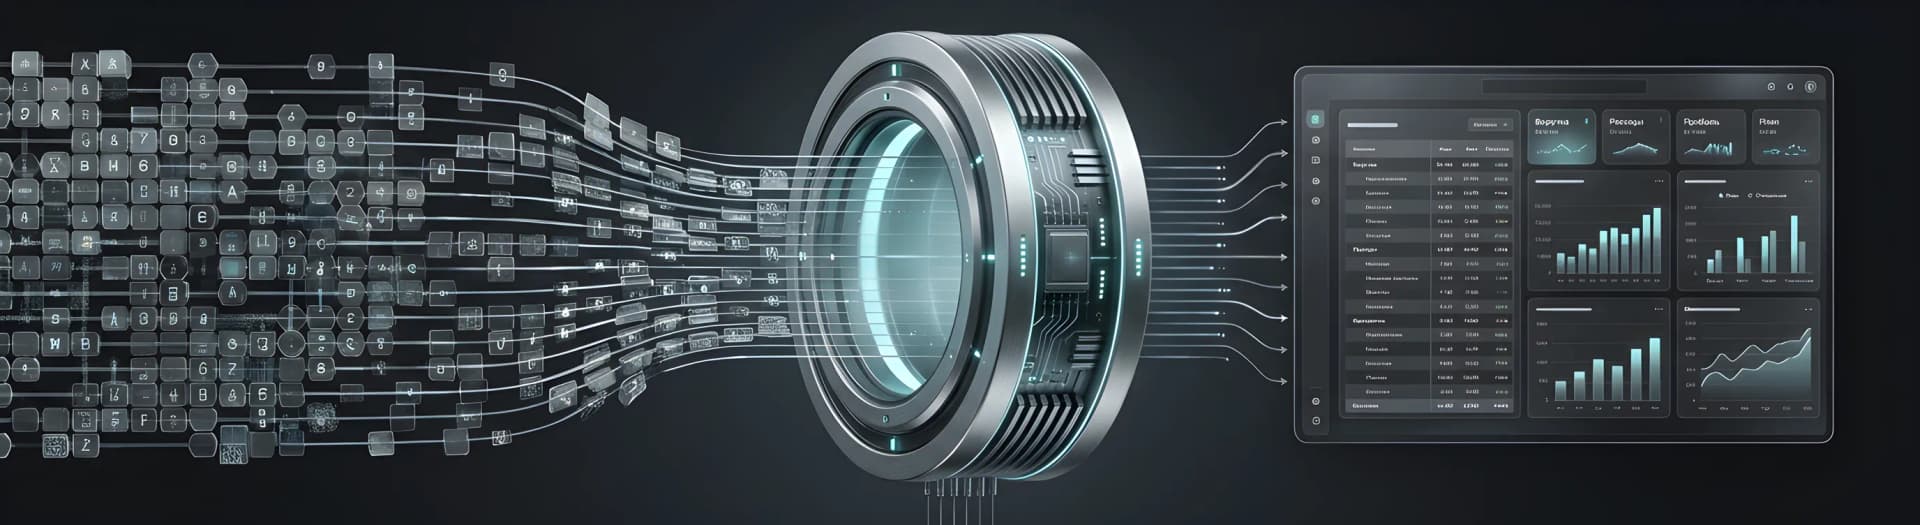
Financial data flowing through a local compute module into a report
  1. 01 · XLSX · CSV · ERP

    Raw data

    Tables and bulk exports from accounting systems are loaded onto the server.

  2. 02 · Local compute

    Exact calculation

    Dedicated data tools calculate the tables, so every number is exact.

  3. 03 · Control

    Anomaly search

    Automatic formula checks, discrepancies and hidden duplicates.

  4. 04 · Human in the loop

    Result

    A verified report, plan vs actual and comments for management.

// Turnkey

All inclusive. From the box to working infrastructure.

Typical target: 2–4 weeks from approved spec to launch
Turnkey delivery: hardware, data and agents
  1. 01 / 04

    Platform

    An AI server with tuned GPU inference, local models, a secure cloud gateway and one browser portal.

  2. 02 / 04

    Data integration

    A corporate knowledge base with RAG and OCR, storage policies and roles for up to 25 people.

  3. 03 / 04

    Agents & rollout

    Agent templates for your office processes, commissioning and team training.

  4. 04 / 04

    Support

    Technical support, model updates and new agents as your tasks grow.

// FAQ

The essentials. Common questions

Does it need the internet?

Local models, knowledge-base search and speech recognition work inside your network, including in a fully isolated mode. Internet access is used only by cloud models, if you choose to connect them.

How many people can work at once?

Office Edition is built for a team of up to 25. The load balancer spreads requests: chats answer instantly, heavy documents are processed in the background.

Which models run on the server?

Locally: Qwen 3.8, Qwen3 Coder 30B, Qwen3-VL 30B, gpt-oss 20B, Llama 4, Gemma 4, Nemotron, Whisper, FLUX and GLM-OCR. By your policy: GPT, Claude, Gemini, Mistral, DeepSeek, GLM, Qwen Max and Kimi.

Does it comply with 152-FZ?

The architecture covers the key requirements of 152-FZ: personal data is stored and processed on a server in your office in Russia, access is role-based and every action is logged. The operator prepares its organisational documents, and we provide the description of the protection measures.

How does it connect to our systems?

Through APIs and connectors: email, CRM, ERP, file storage and messengers. Employees work in the browser, through the API or in OpenCode.

How long does the launch take?

The typical target is 2–4 weeks from the approved spec: server delivery and setup, the knowledge base, agents for your processes and team training.

// Start with an audit

Your data. The full power of AI.

An engineer will propose a configuration, agents and a rollout plan for your team.

  • Free AI audit
  • Fixed-price proposal
  • NDA on request
Step 2 of 4 · Industry
Your answers — tap to change
Your industry

Pick an option — the next question opens itself

Data protected Reply < 24h Free estimate