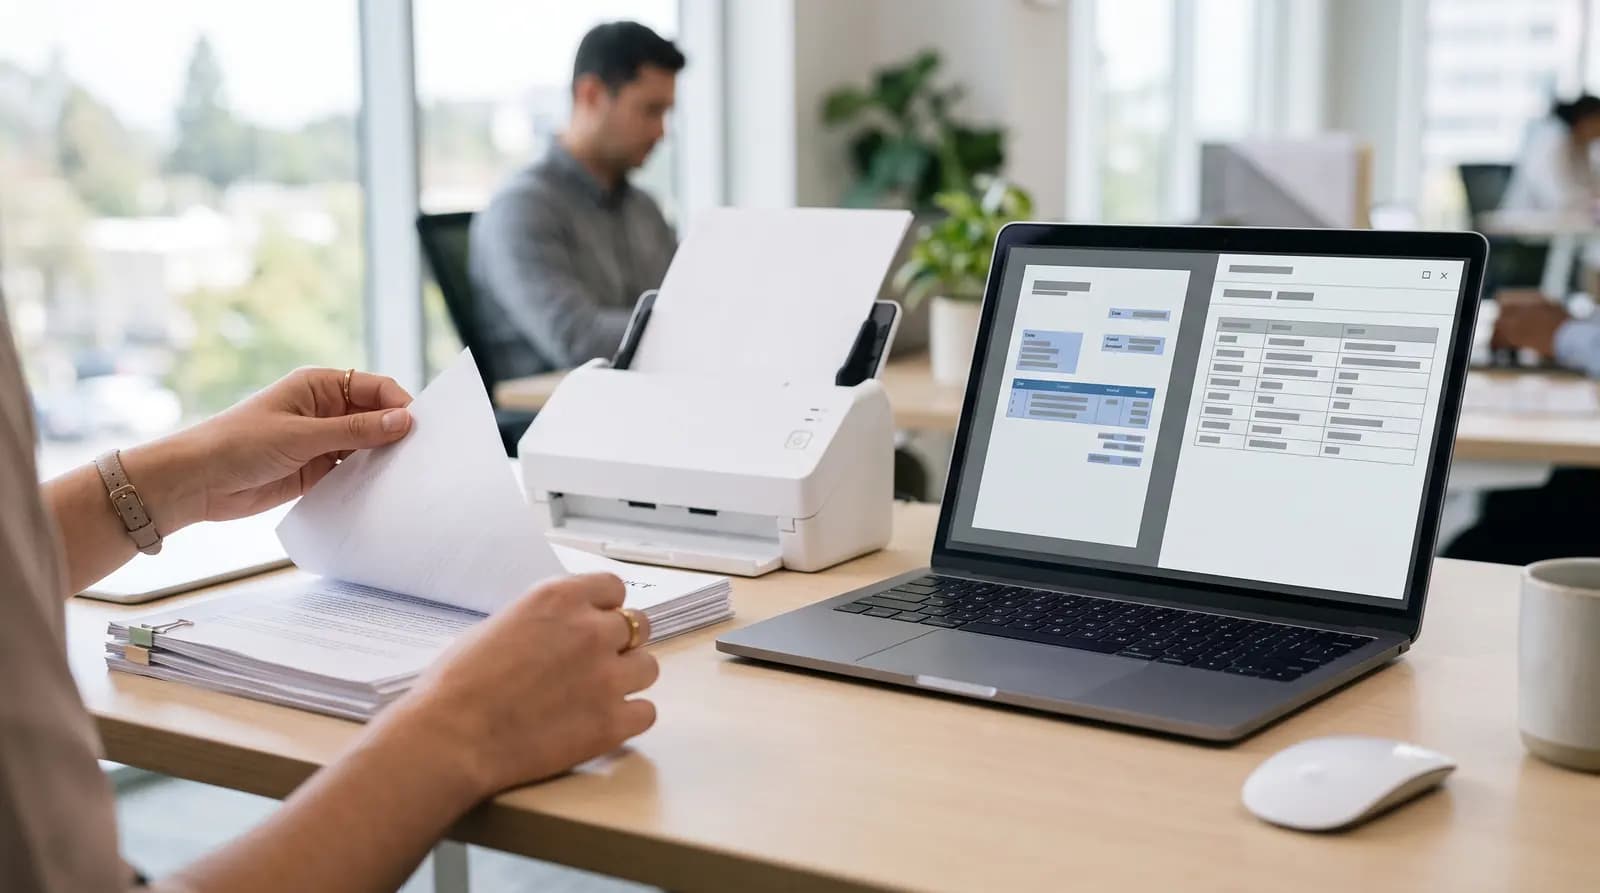
Thousands of pages, read, checked and cited
OCR, extraction and search turn documents into data. Every answer links to the exact quote.
- Data extracted to ERP
- Answers with citations
- On-prem on request
- Timeline: Pilot 4–8 weeks
Four parts of one result
- 01
OCR & parsing
Scans, PDFs and photos recognised with tables and structure intact.
- 02
Extraction
Parties, amounts, deadlines and line items exported to JSON, Excel or ERP.
- 03
Cited search
Answers grounded in the source, with a link to the page.
- 04
Checks
Requirement checklists, contract comparisons and discrepancy reports.
What the pilot targets
- less manual data entry (typical target)
- 60–80%
- of answers linked to a source quote
- 100%
- weeks to a working pilot (typical)
- 4–8
Ranges are typical pilot targets; your own numbers are measured during the pilot. Industry figures name their source.
Where it already works
Short answers
Can it read scans and photos?
Yes. We test accuracy on your samples first and route low-confidence fields to a person.
How do you keep answers accurate?
Answers come only from retrieved fragments, and every claim links to its source.
Can documents stay inside our network?
Yes. OCR, search and the language model can all run on a private server.
Turn your archive into answers
Share sample documents under NDA — we'll show extraction accuracy on your own files.
Free estimate · NDA on request · Reply within 24 hours
- #01
Samples
We agree fields, document types and accuracy targets.
- #02
Pipeline
OCR, extraction and search tested on your files.
- #03
Rollout
Connected to your systems, with accuracy monitored.